projects/adversarial-lab
Adversarial Lab
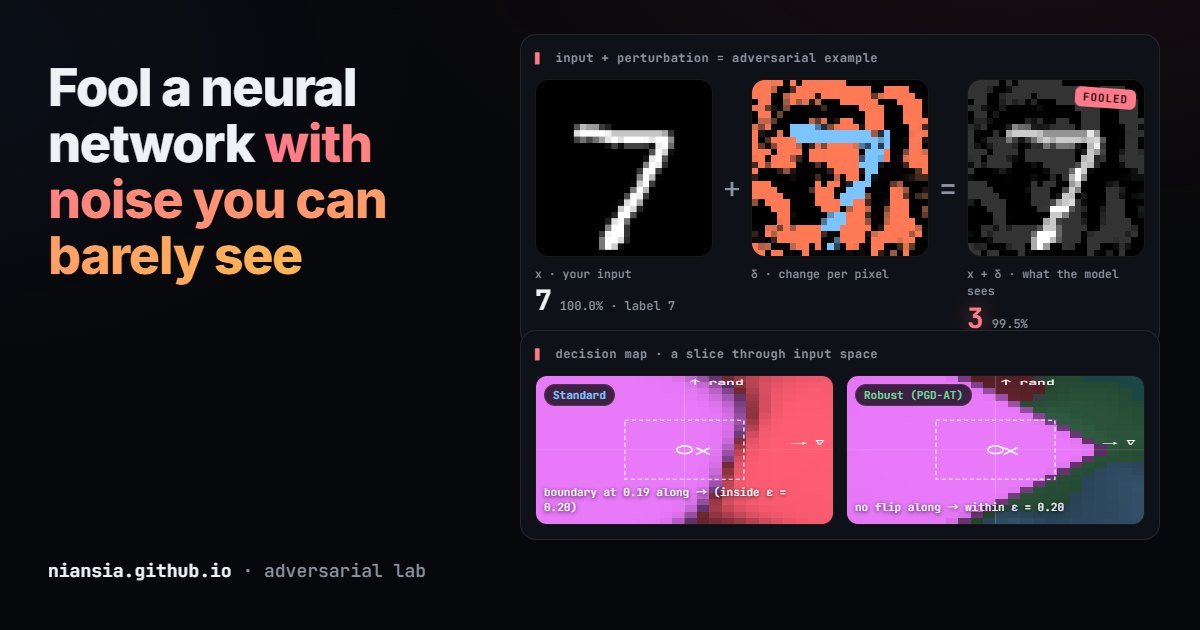
An in-browser playground for adversarial attacks: draw or pick an MNIST digit, attack a CNN with FGSM, PGD or targeted PGD under an L∞ budget, watch the prediction flip step by step, and compare it with a PGD adversarially trained model through gradients, transfer and decision maps of input space. The attacks' gradients are computed in plain JavaScript on the visitor's CPU.
Evidence
On 2,000 MNIST test images under PGD-40: the standard model falls from 98.95% clean accuracy to 0.2% at ε = 0.2, while the adversarially trained model keeps 92.2% at ε = 0.2 and 85.3% at ε = 0.3 (97.92% clean). Gradient-masking checks (PGD below FGSM and below transfer at every ε), JavaScript gradients matched to PyTorch within 1e-8, CPU-only training and evaluation scripts.
This is a lightweight page for sharing. The full, interactive version lives in the terminal portfolio.